Architecture
Ilum is a modular data lakehouse platform built on Kubernetes. It combines Apache Spark, Trino, and DuckDB into a unified multi-engine architecture, managed through a single control plane (ilum-core) and deployed entirely via Helm charts. Ilum follows an "all-in-one but optional" philosophy - every component beyond ilum-core can be enabled or disabled independently, allowing deployments to range from a lightweight development setup to a full enterprise data platform.
The platform is built around several key architectural principles:
- Decoupled compute and storage - processing engines and data storage scale independently
- Stateless core - ilum-core holds no in-memory state, enabling horizontal scaling and crash recovery
- Open standards - OpenAPI REST, JDBC/ODBC, Apache Iceberg/Delta/Hudi table formats, OpenLineage for lineage
- Kubernetes-native - all workloads run as pods with native resource management, scheduling, and observability. Compatible with any CNCF-compliant distribution including Red Hat OpenShift, EKS, AKS, GKE, k3s, Rancher, and bare-metal Kubernetes
Key Components
                        ┌─────────────┐
                        │   ilum-ui   │
                        │  (React)    │
                        └──────┬──────┘
                               │ REST API
        ┌──────────┐    ┌──────▼──────┐    ┌──────────────┐
        │ ilum-cli │────▶  ilum-core  ◀────│   MongoDB    │
        └──────────┘    └──┬───┬───┬──┘    └──────────────┘
                           │   │   │
              ┌────────────┘   │   └────────────┐
              │                │                │
     ┌────────▼───────┐ ┌──────▼─────┐ ┌───────▼────────┐
     │  Kafka / gRPC  │ │  Catalog   │ │ Object Storage │
     │  (messaging)   │ │  Layer     │ │ (MinIO / S3)   │
     └────────┬───────┘ └─────┬──────┘ └───────┬────────┘
              │               │                │
     ┌────────▼───────────────▼────────────────▼────────┐
     │              Compute Clusters                    │
     │         Spark  ·  Trino  ·  DuckDB  ·  SQL       │
     └──────────────────────────────────────────────────┘
-
ilum-core - The central control plane. Manages cluster lifecycle, job scheduling, session management, and REST API exposure (OpenAPI 3.0). Stateless by design - all persistent state is stored in MongoDB, making ilum-core horizontally scalable and crash-recoverable.
-
ilum-ui - React-based web console for managing clusters, submitting jobs, browsing SQL results, configuring security, and monitoring workloads. Communicates exclusively with ilum-core via REST API.
-
ilum-cli - Command-line interface for scripting and automation. Supports all ilum-core REST API operations including job submission, cluster management, and configuration. Useful for CI/CD pipelines and headless environments.
-
Kubernetes Cluster - The primary execution environment. Spark jobs run as Kubernetes pods with configurable executor counts, resource limits, and node affinities. Ilum manages the full pod lifecycle.
-
Object Storage - S3-compatible storage (MinIO, Ceph, RustFS, AWS S3, GCS, Azure Blob) serves as the persistent data layer. All table data, job artifacts, and Spark event logs are stored here, decoupled from compute.
-
MongoDB - Internal metadata store for job history, cluster configuration, user accounts, session state, and operational data. Supports replica sets for high availability.
-
Messaging Layer (Kafka / gRPC) - Handles communication between ilum-core and running Spark jobs. See Communication Types for details.
-
Catalog Layer - Persistent metadata services (Hive Metastore, Nessie, Unity Catalog, DuckLake) that enable SQL access across all engines. See Data Catalog Layer for details.
Integrated Modules
All modules below are optional Helm-deployed components that share authentication, networking, and catalog configuration with ilum-core:
| Category | Modules |
|---|---|
| Orchestration | Airflow, Kestra, n8n |
| Notebooks | JupyterLab, JupyterHub, Zeppelin |
| BI & Visualization | Superset, Streamlit |
| ML & AI | MLflow, AI Data Analyst |
| Data Catalogs | Hive Metastore, Nessie, Unity Catalog, DuckLake |
| Observability | Grafana, Prometheus, Loki, Marquez |
| Version Control | Gitea |
Each module is enabled via a single Helm flag and automatically inherits cluster networking, LDAP/OAuth2 authentication, and catalog connection settings. See Overview for detailed feature descriptions.
Workflow
Batch Job Workflow
- A user submits a Spark job via the ilum-ui, REST API, or ilum-cli, specifying the job JAR/Python file, Spark configuration, and target cluster.
- ilum-core validates the request, schedules the job, and creates a Spark driver pod on the target Kubernetes cluster.
- The Spark driver provisions executor pods according to the configured parallelism. Executors scale horizontally across cluster nodes.
- The job executes, reading from and writing to object storage through the catalog layer.
- Results and execution metadata are returned to ilum-core and stored in MongoDB. Users view results in the UI or fetch them via the REST API.
Interactive Session Workflow
- A user creates an interactive session (via UI, API, or CLI), which launches a long-running Spark application pod.
- The session remains alive, ready to accept code execution requests without Spark initialization overhead.
- Users submit code snippets (Scala, Python, SQL) via REST API. Each snippet executes within the existing Spark context and returns results immediately.
- Multiple users can share a session through Code Groups - shared Spark contexts that enable collaborative analysis while isolating variable namespaces.
- The session terminates on explicit shutdown or after a configurable idle timeout.
For step-by-step guides, see Run a Spark Job and Interactive Jobs.
Communication Types
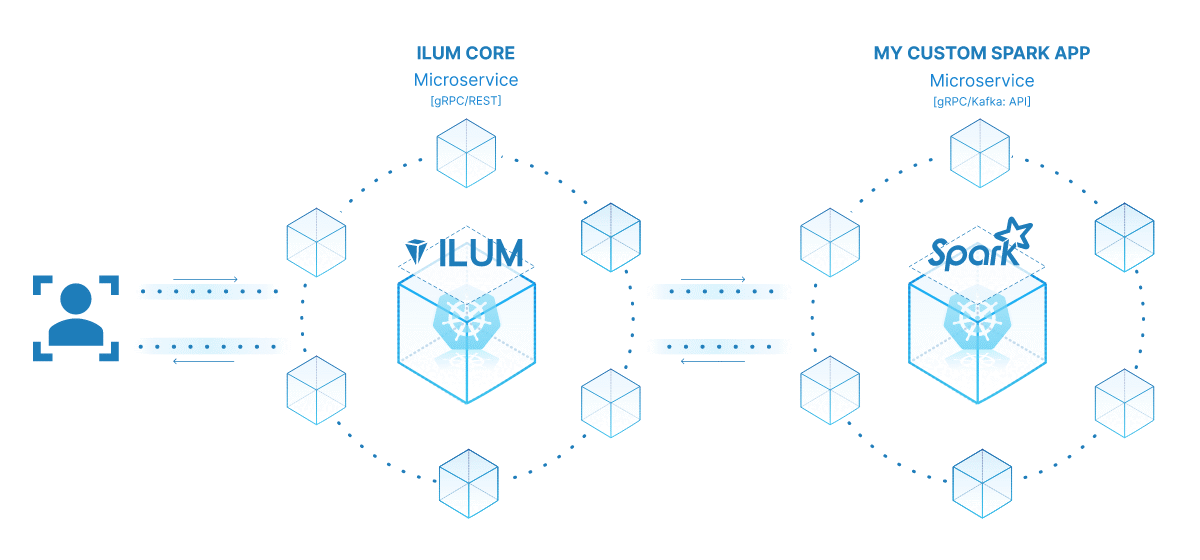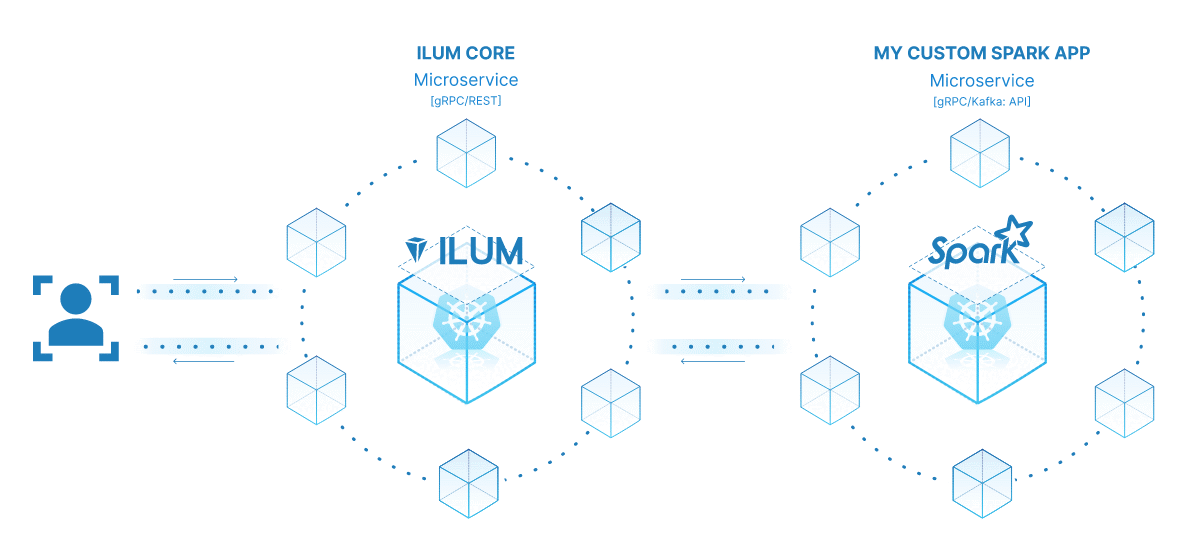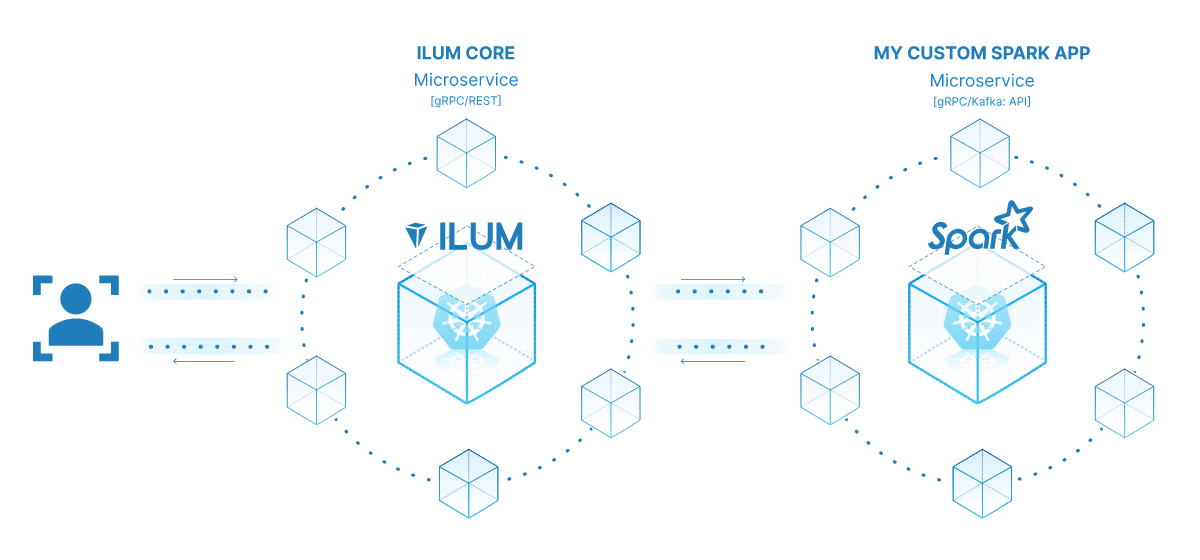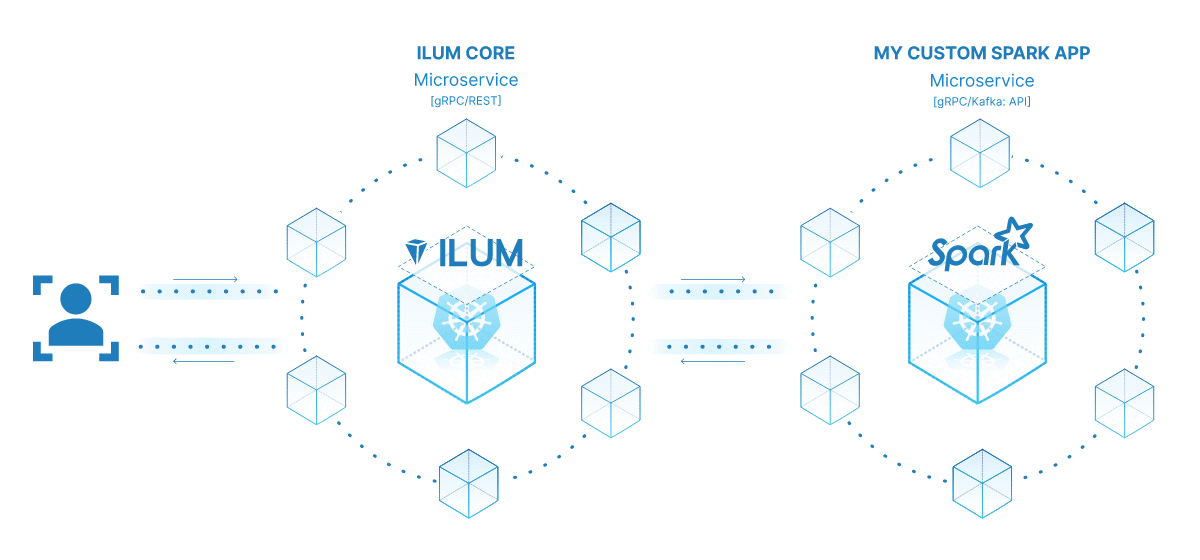
Ilum supports two forms of communication between Spark jobs and ilum-core: Apache Kafka and gRPC.
Apache Kafka Communication
Ilum's integration with Apache Kafka facilitates reliable and scalable communication, supporting all of Ilum's features, including High Availability (HA) and scalability. All event exchanges are conducted via automatically created topics using Apache Kafka brokers.
gRPC Communication (default)
As an alternative, gRPC can be used for communication. This option simplifies the deployment process by eliminating the need for Apache Kafka during installation. gRPC establishes direct connections between ilum-core and Spark jobs, removing the requirement for a separate message broker. However, using gRPC does not support High Availability (HA) for ilum-core under the current implementation. While ilum-core can be scaled, existing Spark jobs will continue communicating with the same ilum-core instances.
Comparison
| Feature | Apache Kafka | gRPC |
|---|---|---|
| High Availability | Yes - ilum-core replicas share state via topics | No - direct point-to-point connections |
| Scalability | Horizontally scalable with partitioned topics | Limited to single ilum-core affinity |
| Deployment Complexity | Requires Kafka cluster (3+ brokers recommended) | Zero additional infrastructure |
| Recommended For | Production, multi-replica, HA environments | Development, testing, single-node setups |
Start with gRPC for development and testing. Switch to Kafka when deploying to production or enabling HA. See Production Deployment for HA configuration.
Multi-Engine Query Architecture
Ilum provides three query engines through a unified SQL gateway. This architecture allows users to submit SQL queries via standard JDBC/ODBC interfaces and have them routed to the most appropriate engine.
┌──────────────────────┐
│   JDBC / ODBC        │  BI tools, CLI, applications
│   Clients            │
└─────────┬────────────┘
          │ Thrift Binary Protocol
┌─────────▼────────────┐
│                      │  Session management, engine routing,
│     SQL Gateway      │  authentication, connection pooling
└──┬──────┬─────────┬──┘
   │      │         │
┌──▼──┐ ┌─▼───┐ ┌──▼───┐
│Spark│ │Trino│ │DuckDB│   Engine selection per session
│ SQL │ │     │ │      │
└──┬──┘ └──┬──┘ └──┬───┘
   │       │       │
┌──▼───────▼───────▼───┐
│   Catalog Layer      │  Hive Metastore / Nessie
├──────────────────────┤
│   Storage Layer      │  MinIO / S3 / GCS / HDFS
└──────────────────────┘
Spark SQL
On-demand sessions with DAG-based parallel execution. Spark SQL is the most versatile engine - it handles ETL, batch processing, ML pipelines, and complex analytical queries. Executors are provisioned dynamically via Kubernetes and can scale from zero to hundreds of pods. Best suited for heavy transformations, large-scale joins, and workloads that benefit from distributed shuffle.
Trino
Always-on MPP (Massively Parallel Processing) engine with a coordinator-worker topology. Trino uses pipelined execution to deliver sub-second interactive query latency on large datasets. Workers remain running for instant query response. Best suited for interactive analytics, dashboarding, and ad-hoc exploration.
DuckDB
Embedded analytical engine running inside the ilum-core process. DuckDB provides zero-overhead local query execution with no pod provisioning or network latency. Best suited for lightweight analytics, small dataset queries, and rapid prototyping.
Engine Selection Guide
| Use Case | Recommended Engine |
|---|---|
| ETL / large-scale batch processing | Spark SQL |
| Interactive dashboards and BI queries | Trino |
| Complex ML pipelines | Spark SQL |
| Ad-hoc exploration on large datasets | Trino |
| Quick queries on small datasets | DuckDB |
| Streaming ingestion (Structured Streaming) | Spark SQL |
All three engines access the same data through the shared catalog layer and object storage, enabling users to choose the right engine per workload without data movement. See SQL Viewer for engine configuration and Performance for optimization details.
Data Catalog Layer
Data catalogs provide the persistent metadata layer that enables SQL access, schema management, and multi-engine data sharing. When a Spark job or Trino query creates a table, the catalog records its schema, location, and format so that any engine can access it later.
Ilum supports four catalog implementations:
Hive Metastore (default)
PostgreSQL-backed metadata service, automatically deployed and configured by Helm. Compatible with Spark, Trino, and Superset out of the box. Provides the broadest ecosystem compatibility and is the recommended default for most deployments.
Nessie
Git-like catalog for Apache Iceberg tables. Supports branching, tagging, and merging of table metadata - enabling CI/CD workflows for data. Create a branch, experiment with schema changes or data transformations, and merge only when validated.
Unity Catalog
Three-level namespace model (catalog, schema, table) with governance-focused access control. Provides a familiar structure for organizations migrating from Databricks or requiring fine-grained catalog-level permissions.
DuckLake
Lightweight embedded catalog optimized for DuckDB. Stores metadata directly in a DuckDB database file, ideal for local development and single-engine DuckDB workloads.
Catalog Integration
Spark jobs launched through ilum are automatically configured with catalog connection parameters at startup - no manual configuration required. Trino and Superset also receive catalog configuration via Helm values.
Table Format Support
| Catalog | Delta Lake | Apache Iceberg | Apache Hudi | Parquet |
|---|---|---|---|---|
| Hive Metastore | Yes | Yes | Yes | Yes |
| Nessie | No | Yes | No | No |
| Unity Catalog | Yes | Yes | No | Yes |
| DuckLake | No | No | No | Yes |
See Data Catalogs for setup details and Ilum Table for the unified table abstraction.
Cluster Types
Ilum simplifies Spark cluster configuration, and once configured, the cluster can be used for various jobs, irrespective of their type or quantity. Ilum currently supports three types of clusters: Kubernetes, Yarn, and Local.
During the initial launch, Ilum automatically creates a default cluster, using the same Kubernetes cluster on which Ilum is installed. If this default cluster is accidentally deleted, you can easily recreate it by restarting the ilum-core pod.
Kubernetes Cluster
Ilum's primary focus is to facilitate easy integration between Spark and Kubernetes. It simplifies the configuration and launch of Spark applications on Kubernetes. To connect to an existing Kubernetes cluster, users need to provide default configuration information, such as the Kubernetes API URL and authentication parameters. Ilum supports both user/password and certificate-based authentication methods. Multiple Kubernetes clusters can be managed by Ilum, provided they are accessible. This feature enables the creation of a hub for managing numerous Spark environments from a single location.
Ilum is compatible with any CNCF-compliant Kubernetes distribution:
- Managed cloud: Google Kubernetes Engine (GKE), Amazon EKS, Azure AKS, DigitalOcean Kubernetes
- Enterprise: Red Hat OpenShift / OKD
- Lightweight: k3s, Rancher, MicroK8s
- Bare metal: Self-managed Kubernetes installations
- Local development: Minikube, k3d, Docker Desktop
Yarn Cluster
Ilum also supports Apache Yarn clusters, which can be easily configured using Yarn configuration files present in the Yarn installation.
Local Cluster
The local cluster type runs Spark applications where ilum-core is deployed, meaning it runs Spark applications either inside the ilum-core container when deployed on Docker/Kubernetes, or on the host machine when deployed without an orchestrator. This cluster type is suitable for testing purposes due to its resource limitations.
Comparison
| Feature | Kubernetes | Yarn | Local |
|---|---|---|---|
| Production Ready | Yes | Yes | No (testing only) |
| High Availability | Yes | Yes (via YARN RM HA) | No |
| Auto-Scaling | Yes (K8s autoscaler) | Yes (YARN node managers) | No |
| Multi-Cluster | Yes | Yes | N/A |
| Dynamic Executor Allocation | Yes | Yes | Limited |
A single ilum instance can manage multiple clusters of different types simultaneously, enabling hybrid K8s + Yarn deployments - useful for organizations migrating from Hadoop to Kubernetes. See Clusters and Storages for configuration details.
Decoupled Compute-Storage Architecture
Ilum follows a decoupled compute-storage architecture where processing engines and data storage are independent, horizontally scalable layers. This separation is fundamental to ilum's design and enables independent scaling, multi-engine access, and cost-efficient resource utilization.
┌─────────────────────────────────────────────────────────────┐
│                    Compute Layer                            │
│  ┌──────────┐  ┌──────────┐  ┌──────────┐                   │
│  │  Spark   │  │  Trino   │  │  DuckDB  │   Engines         │
│  │ Executors│  │ Workers  │  │(embedded)│   scale           │
│  └────┬─────┘  └─────┬────┘  └──────┬───┘   independently   │
│       │              │              │                       │
├───────┼──────────────┼──────────────┼───────────────────────┤
│       │ Catalog Layer (Hive Metastore / Nessie)             │
├───────┼──────────────┼──────────────┼───────────────────────┤
│       │              │              │                       │
│  ┌────▼──────────────▼──────────────▼─────┐                 │
│  │           Storage Layer                │                 │
│  │  MinIO / S3 / GCS / WASBS / HDFS       │   Storage       │
│  │  (Iceberg / Delta / Hudi / Parquet)    │   scales        │
│  └────────────────────────────────────────┘   independently │
└─────────────────────────────────────────────────────────────┘
Benefits of this architecture:
- Independent scaling: Add more Spark executors or Trino workers without provisioning additional storage, and vice versa
- Multi-engine access: Multiple compute engines can read from and write to the same datasets concurrently, mediated by table formats (Iceberg, Delta) that provide ACID guarantees
- Cost efficiency: Compute resources can be released when not in use (e.g., Spark dynamic allocation, auto-pause) while data remains persistently available in object storage. Scale compute to zero during off-hours - storage costs persist, but expensive compute does not
- Engine flexibility: Choose the right engine for each workload - Spark for ETL, Trino for interactive analytics, DuckDB for lightweight queries - all accessing the same data
- Catalog-mediated consistency: The catalog layer ensures all engines see a consistent view of table metadata, enabling safe concurrent reads and writes across Spark, Trino, and DuckDB
Scalability
ilum-core was designed with scalability in mind. Being completely stateless, ilum-core can recover its entire existing state after a crash, making it easy to scale up or down based on load requirements.
Ilum supports multiple scaling dimensions:
- ilum-core horizontal scaling - Deploy multiple stateless replicas behind a load balancer. Requires Kafka for inter-replica coordination
- Spark dynamic executor allocation - Executors scale up and down automatically based on workload. Idle executors are released after a configurable timeout
- Kubernetes HPA - Horizontal Pod Autoscaler can manage always-on services (Trino workers, ilum-core replicas) based on CPU/memory metrics
- Cluster autoscaler - Node-level scaling via Kubernetes Cluster Autoscaler or cloud provider auto-scaling groups, triggered when pending pods cannot be scheduled
- Resource quotas - Kubernetes namespaces and ilum resource controls enforce per-tenant resource limits, preventing any single workload from monopolizing cluster resources
See Resource Control and Production Deployment for configuration details.
High Availability
ilum-core and its required components support High Availability (HA) deployments. An HA deployment necessitates the use of Apache Kafka as the communication type, as gRPC does not support HA.
Recommended HA Configuration
| Component | Minimum Replicas | Notes |
|---|---|---|
| ilum-core | 3 | Stateless; requires Kafka for HA coordination |
| MongoDB | 3 | Replica set with automatic failover |
| Apache Kafka | 3 | KRaft quorum or ZooKeeper-based |
| MinIO | 4 | Erasure coding for data durability |
Failure Domain Mitigation
- Pod anti-affinity - Spread replicas of each component across different nodes to survive single-node failures
- Namespace isolation - Deploy ilum infrastructure (Kafka, MongoDB, MinIO) in a dedicated namespace separated from user workloads
- Zone-aware scheduling - In multi-zone clusters, use topology spread constraints to distribute pods across availability zones
See Production Deployment for the full HA deployment guide.
Observability Architecture
Ilum provides three observability pillars - metrics, logs, and lineage - through optional Helm-deployed modules.
Metrics
Spark exposes execution metrics via the built-in PrometheusServlet. Ilum deploys PodMonitor resources that Prometheus scrapes automatically. Pre-configured Grafana dashboards visualize executor utilization, job duration, shuffle I/O, and GC pressure.
Spark Executor → PrometheusServlet → PodMonitor → Prometheus → Grafana
Logs
Container logs from all Spark driver and executor pods flow through the standard Kubernetes logging pipeline. When Loki is enabled, a Promtail DaemonSet collects logs from each node and ships them to Loki for centralized LogQL querying.
Container stdout → Promtail DaemonSet → Loki → LogQL queries
Data Lineage
The OpenLineage Spark Listener captures table-level and column-level lineage events during job execution. These events are sent to the Marquez API, which stores them and exposes lineage graphs through the ilum UI (ERD and directed graph views).
Spark Job → OpenLineage Listener → Marquez API → Lineage UI
Spark History Server
For deep post-execution analysis, Spark History Server reads event logs from object storage and provides detailed DAG visualizations, stage breakdowns, and task-level metrics.
All observability components are optional and enabled via Helm flags. See Monitoring for metrics and log configuration, and Data Lineage for lineage setup.
Security
Ilum provides a comprehensive security architecture covering authentication, authorization, data access control, and network security.
Authentication
Ilum supports multiple authentication methods:
- Internal LDAP - Embedded OpenLDAP server deployed via Helm for standalone deployments
- External LDAP/AD - Connect to existing Active Directory or LDAP directories
- OAuth2/OIDC - Integration via ORY Hydra supporting Okta, Azure AD, Google, and Keycloak as identity providers
Authorization
- RBAC - Role-based access control with two modes: unrestricted (development - all users have full access) and restricted (production - permissions are enforced per role)
- ABAC - Attribute-based access control using data classification tags for fine-grained policy decisions
Data Access Control
- Row-level filters - Restrict query results based on user attributes (e.g., region, department)
- Column-level masking - Redact or hash sensitive columns (PII, financial data) based on user roles
- Hierarchical privileges - Grant access at catalog, schema, table, or column level
Network Security
- TLS/mTLS - Encrypted communication between ilum-core, Spark jobs, and integrated services
- Kubernetes Network Policies - Restrict pod-to-pod communication to authorized paths
Secrets Management
- Kubernetes Secrets - Native secret storage for credentials, certificates, and API keys
- External vault integration - Support for mounting secrets from external KMS providers
ilum as Identity Provider
Ilum can act as an OAuth2 provider for integrated services. When enabled, Airflow, Superset, Grafana, Gitea, and MinIO authenticate users through ilum's OAuth2 endpoints - providing single sign-on across the entire platform.
See Security for the full security guide, Data Access Control for row/column policies, and OAuth2 for OIDC configuration.